Work / LLM-Digest
LLM-Digest
An AI analyst I run myself: every hour it reads 127 sources, runs a nine-stage LLM pipeline with a fallback model behind every stage, and writes one page of market conclusions that trace back to their posts.
- Next.js 16
- React 19
- TypeScript
- Vercel AI SDK v6
- SQLite FTS5
- Drizzle
- NVIDIA embeddings
- Cloudflare Tunnel
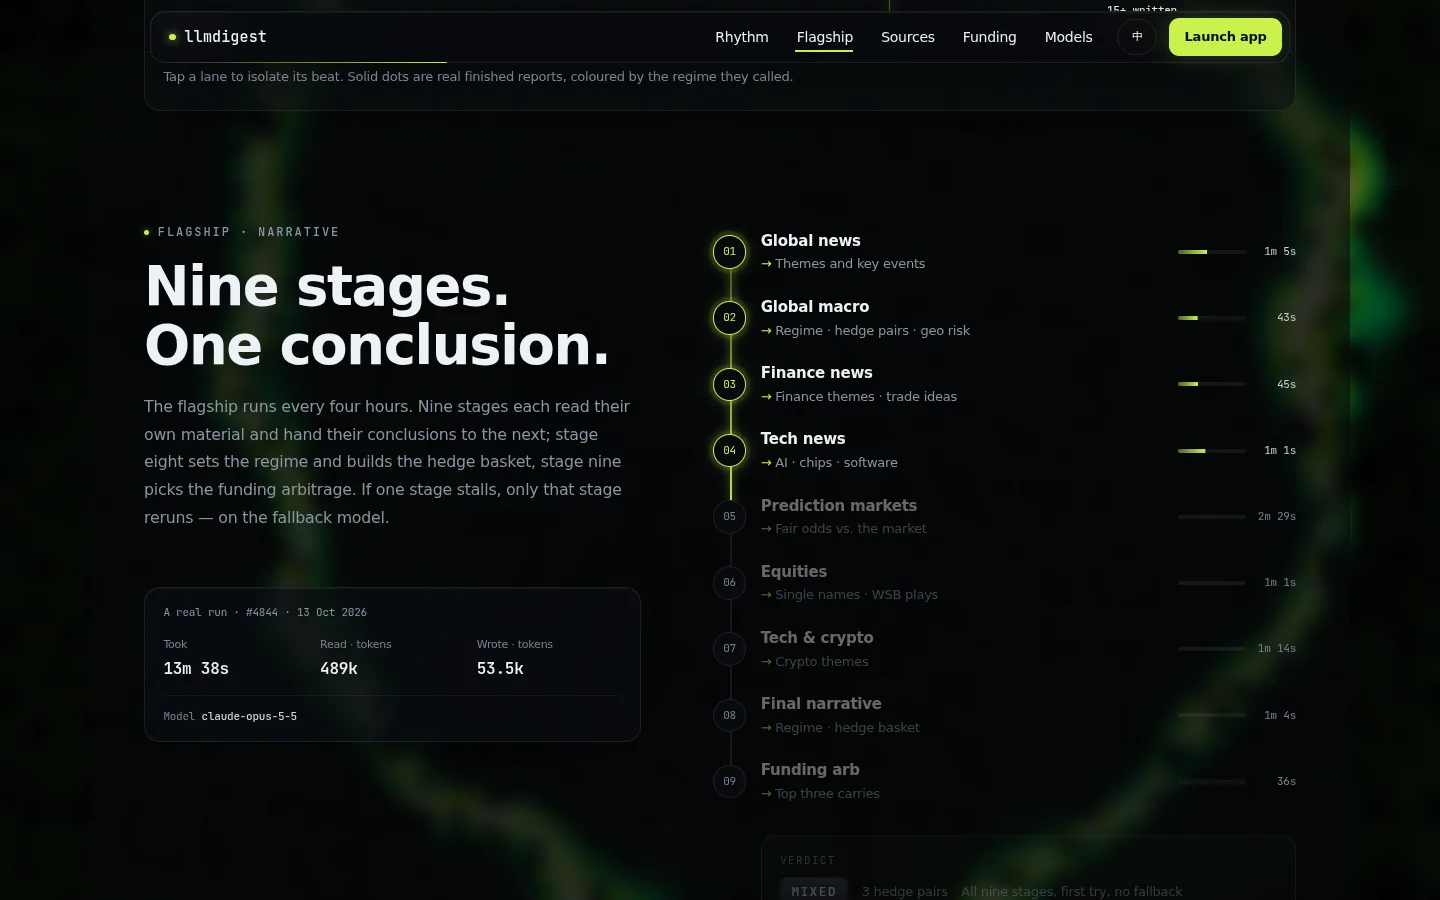
Replay of flagship run #4844, 13 Oct 2026, about 14× faster. The stall is simulated.
- 01Global newsThemes and key events1m 05s
- 02Global macroRegime, hedge pairs, geo risk43s
- 03Finance newsFinance themes, trade ideas45s
- 04Tech newsAI, chips, software1m 01s
- 05Prediction marketsFair odds against the market2m 29s
- 06EquitiesSingle names, WSB plays1m 01s
- 07Tech and cryptoCrypto themes1m 14s
- 08Final narrativeRegime and hedge basket1m 04s
- 09Funding arbTop three carries36s
- Took
- 13m 38s
- Read, tokens
- 489k
- Wrote, tokens
- 53.5k
Writing with claude-opus-5-5
The problem
Market-moving news arrives as roughly 39,000 posts a week from about 2,000 accounts on X alone, before RSS, Telegram, forums, prediction markets and funding rates. Reading all of it is a job. I wanted the conclusion waiting for me when I wake up, with a way to check any line of it.
LLM-Digest is the AI system I built for that, and I run it every day. Five kinds of report are written on a schedule: hourly, a narrative every four hours, morning, evening and weekly. More than 4,100 so far. Trading books in it are paper only.
The replay above is one real flagship run, #4844 on 13 October 2026: nine stages in 13 minutes 38 seconds, 489k tokens read and 53.5k written, every stage done on the first try. Press Stall this stage to see what happens when a model goes quiet.
How the AI is put together
Feeds are deduplicated by meaning before anything is stored, so the models read one copy of each story. Three readers sit on the store: the nine-stage narrative pipeline, a chat agent that answers questions with retrieval and citations, and a signal reader that turns 65 indicator cells per ticker into one call with an entry, a stop and a target.
All three go through one model layer. Any OpenAI-compatible provider plugs in, each task has a primary and a fallback model, and API keys are encrypted with AES-256-GCM on the server and never reach the browser.
What the AI work involved
- 9stages, typed
A pipeline that hands conclusions forward
Each stage reads its own material and passes a Zod-validated JSON conclusion to the next. Malformed output is repaired with jsonrepair and retried; stage eight sets the regime and builds the hedge basket.
- 3 minstream wall
Fallbacks that rerun one stage, not the run
A byte-level watchdog notices when a stream goes quiet. After three minutes the fallback model takes that stage over and the finished stages stay as they are.
- 6agent tools
Retrieval that cites what it read
The chat agent runs a phased three-step tool loop. It rewrites the question, fuses SQLite FTS5/BM25 hits with 12 web search sources by reciprocal rank fusion, and checks that every citation it gives points at something it actually retrieved.
- 0vector databases
Semantic dedup without a vector DB
NVIDIA embeddings, SimHash and cosine-centroid clustering over in-memory Float32 pools. I benchmarked Qdrant and Postgres first; at this scale the in-process version was simpler and fast enough.
- AnyOpenAI-compatible model
A model layer that outlives the models
Per-provider request pacing, a daily budget in dollars, per-run token and cost tracking, and a repair step that turns text into tool calls for models without native tool use. Chat switches models mid-session without a reload.
- 65cells per ticker
From indicators to one call
Five timeframes by 13 indicator families. Nobody scans that by hand; the model reads all of it and states where to enter, where it is wrong and where to take profit. Every paper trade keeps a thread back to the report and the posts behind it.
Keeping it running
- 374 → <10SQLite stalls an hour
A database that stopped freezing the site
A stall watchdog, time-boxed write slices, an off-thread read worker and a WAL checkpoint thread.
- 44cron jobs
Deadlines on every job
Deadline walls ended silent cron hangs that used to last hours.
- 2.5 min → 3 sdeploy downtime
Staged builds on a self-hosted box
systemd and a Cloudflare Tunnel, with the next build staged before the switch. An audit also found and closed two critical Server Action auth bypasses.
- 242klines of code
- 480commits
- 29pages
- 39API routes
- 82Server Actions
- 1,000+i18n keys
Stack
- AI
- Vercel AI SDK v6
- tool calling
- RAG with RRF
- Zod schemas
- jsonrepair
- NVIDIA embeddings
- SimHash
- App
- Next.js 16
- React 19
- TypeScript
- Server Actions
- next-intl
- WebGL
- Data
- SQLite (WAL, FTS5)
- Drizzle
- croner
- WebSockets
- Ops
- systemd
- Cloudflare Tunnel
- AES-256-GCM key vault
See it running
The public landing page walks through the rhythm, the flagship run, the sources, funding and the model layer. The app behind it is single-operator.
What's next
Brokerage market data for US equities, and folding the WebGL landing branch back into main.